
Doyensec finds AI pentest agents agree on only 7 of 73 flaws
10/03/2026 — 10/03, 01:50·1 sources·1 reports
Story overview
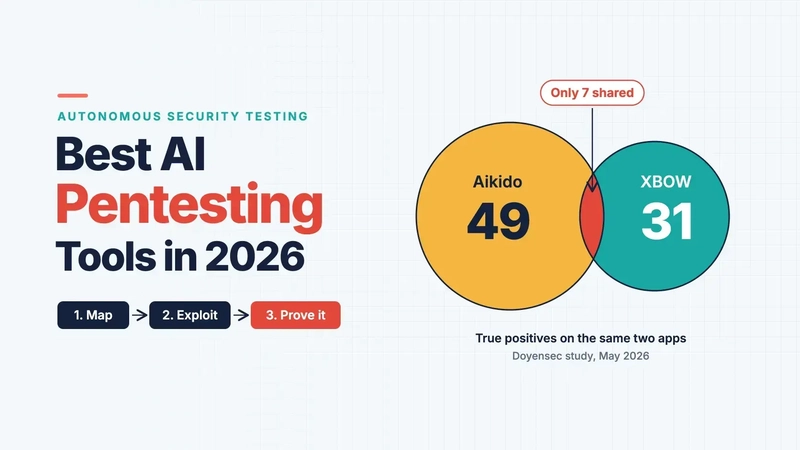
A study from the security firm Doyensec offers some evidence about how well AI pentesting agents actually perform. According to a DEV Community report published on October 3, 2026, the research was carried out in May of this year and found that, across 73 vulnerabilities, two AI pentesting agents reached the same judgment on only 7 of them. That comparison is a measure of consistency between the two agents — whether two separate runs over the same set of vulnerabilities arrive at the same conclusion.
The report frames pentest reports as something companies rarely commission on their own initiative. Sell software to anyone with a security team, and eventually someone will ask for one: a SOC 2 auditor, a procurement questionnaire, an insurance renewal. The usual answer is a consultancy that tests the app once, writes a PDF, and is out of date by the next deploy. AI pentesting agents promise to run that test continuously, and according to the report, 2026 is the year when some evidence about how these tools actually behave is finally starting to appear.
The figure of 7 matching judgments out of 73 vulnerabilities is presented as an indication that reliability gaps remain for this class of tooling. The available material does not name the two agents, identify the models behind them, or describe the testing methodology, and it does not offer further details from the study itself.
AI-generated from 1 reports · updated 1 hour ago
Latest turnA May 2026 study by security firm Doyensec offers some of the first hard evidence on AI pentesting agents: across 73 bugs, two agents agreed on only 7. Vendors pitch these tools as continuous replacements for one-off consultancy reports, but the low agreement rate points to a real reliability gap.
Reports on this story headlines open the original
A May 2026 study by security firm Doyensec offers some of the first hard evidence on AI pentesting agents: across 73 bugs, two agents agreed on only 7. Vendors pitch these tools as continuous replacements for one-off consultancy reports, but the low agreement rate points to a real reliability gap.
DEV Community · AIAI score 78
Other stories people are talking about
- 625SurgeNVIDIA launches 64GB DGX Spark desktop AI computer at $4,9997 sources
- 495RisingGoogle releases Gemini 4 Argon as next-gen frontier AI model14 sources
- 389NewApple tightens macOS Full Disk Access over AI agent risks4 sources
- 224SurgeMicrosoft AI releases MAI-Transcribe-2-Streaming real-time transcription model3 sources
- 191NewAnthropic launches Claude Frontier Academy with $100M2 sources
- 179NewHugging Face open-sources AstaBrief for fast report generation2 sources
How is heat calculated?About the methodHide
Heat counts how many independent sources covered a story in the last 48 hours: one source counts once no matter how many posts it published, decaying with a 24-hour half-life. What ranks first is what many people are talking about.
This page aggregates public feeds. Headlines and summaries are machine-organized and remain the property of the original authors; verify important facts at the source.
- Surge
- Discussion rising fast
- New
- First report within 6 hours
- Rising
- Still gathering discussion